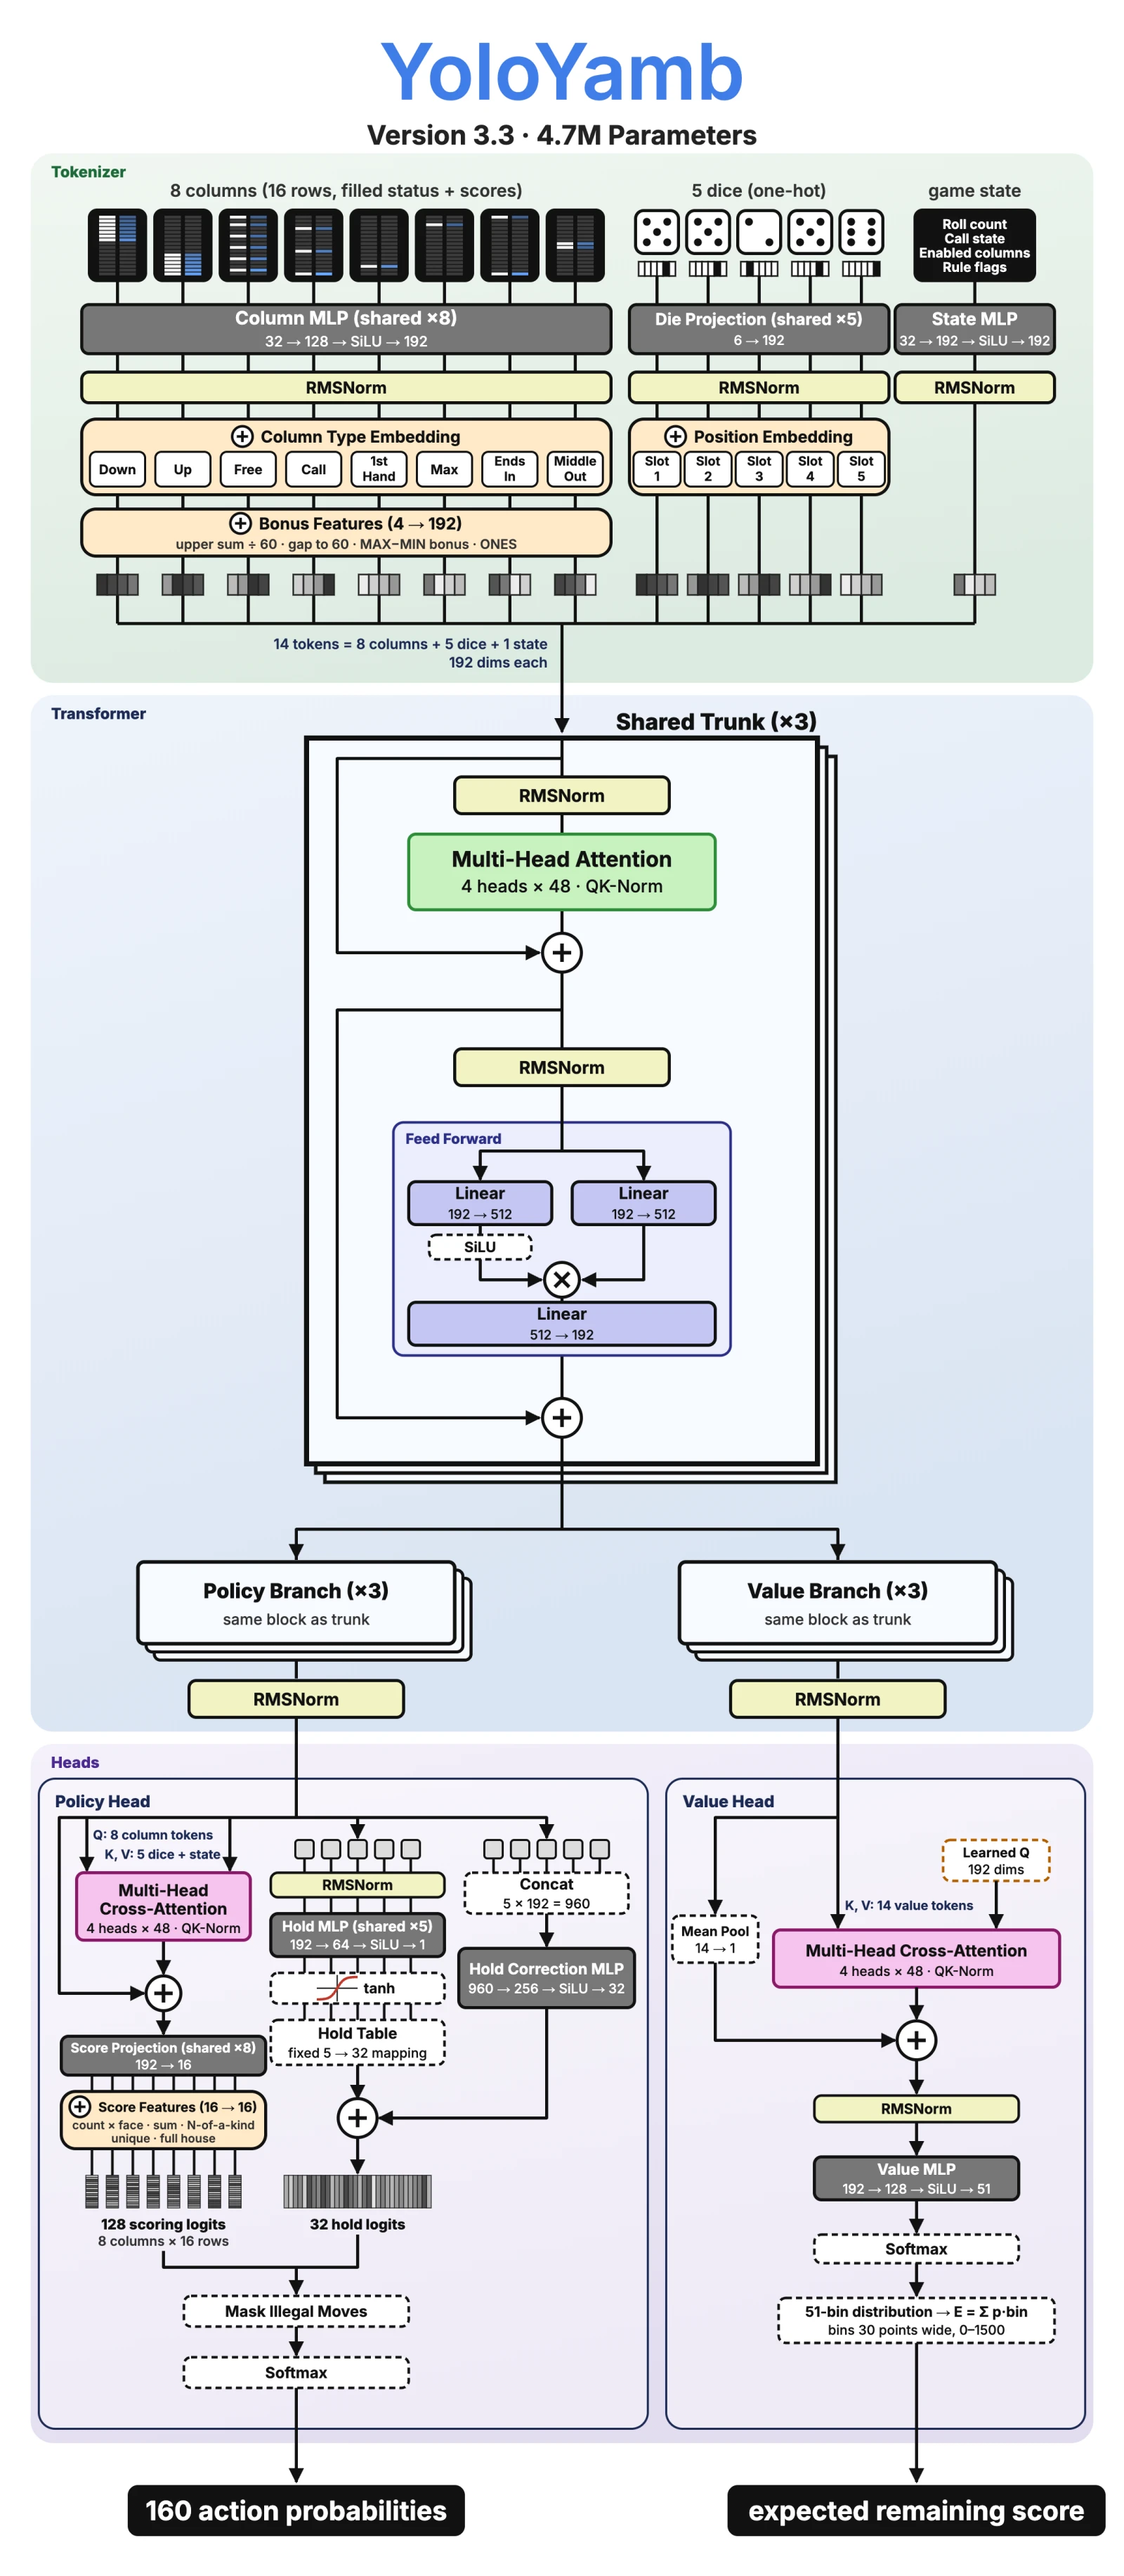
Extended Yumbee with a 4.7M-parameter transformer model built from scratch and trained to play Yamb through self-play. It plays directly in the browser, averaging an expert-level 1,366 points per game.
The model reads the game state as 14 tokens of 192 dims each (8 columns, 5 dice, and 1 for the game state). Tokens interact through full self-attention in a 3-layer shared trunk, then split into separate 3-layer policy and value branches. For the policy, columns cross-attend to the dice and game state to pick where to score and a hold head picks which dice to keep, totaling 160 possible actions. For the value, mean and attention pooling predict the expected remaining score through a 51-bin distribution.
Training took 200 hours on a single RTX 4090.